New AI factory approach combines digital-twin validation and factory-built infrastructure, with Polar Data Centers deploying the model in Norway.
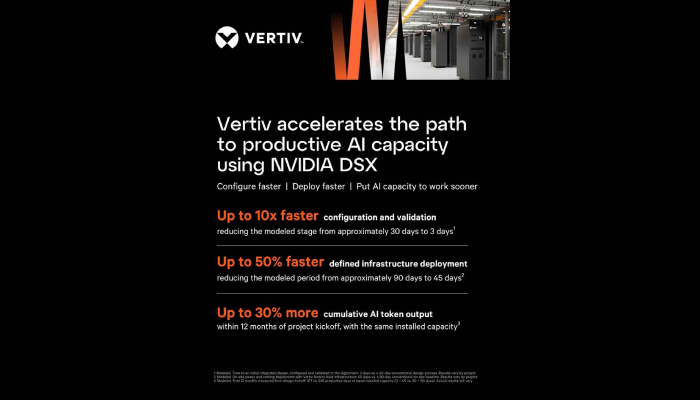
Vertiv and NVIDIA have introduced an AI factory infrastructure approach designed to accelerate data centre deployment and increase productive AI capacity. Under a modelled scenario, the approach could deliver up to 30% more cumulative AI token output in the first 12 months, using the same installed capacity.
Announced at NVIDIA GTC Berlin, the approach combines pre-engineered reference designs, virtual validation and factory-built infrastructure. It integrates NVIDIA’s Vera Rubin DSX AI Factory reference design and Omniverse DSX Blueprint with Vertiv’s power and cooling assets and Dassault Systèmes’ 3DEXPERIENCE agentic platform.
According to Vertiv, virtual configuration and validation could reduce design time from approximately 30 days to three days. Factory-built infrastructure could cut on-site power and cooling deployment from 90 days to 45 days. Combined, these changes could reduce the two stages from 120 days to 48 days, bringing productive AI capacity online around 10 weeks earlier.
The model’s projected 30% improvement is based on 317 versus 245 productive days during the first 12 months, assuming equal installed capacity. Actual results will vary by project.
“Success depends on how quickly operators can move from requirements to productive AI capacity.” — Giordano Albertazzi, CEO, Vertiv
Polar Data Centers is applying the deployment approach to the first 41 MW phase of its AI data centre campus at Herøya, Norway, which is scalable to 100 MW. Vertiv is supplying prefabricated power and thermal modules, SmartRun overhead infrastructure and SmartMod systems.
NVIDIA’s Vera Rubin reference design is intended to align compute, power and cooling requirements from the outset, while digital-twin simulation helps identify integration issues before construction.
The collaboration reflects growing pressure on data centre operators to bring high-density AI infrastructure online faster as demand for computing capacity accelerates.
