The new architecture combines streaming, integration, processing, governance and query capabilities to help AI agents and applications act on continuously updated, governed business information.
Confluent, an IBM company, has introduced Streamhouse, a data architecture designed to give AI agents, applications and analytics systems access to a continuously updated view of enterprise operations. The announcement adds Query as the fifth pillar of Confluent’s Data Streaming Platform, alongside Stream, Connect, Process and Govern, creating a unified foundation for building Streamhouse architectures.
The move addresses a growing challenge in enterprise AI: agents often draw information from systems that update at different times, leaving them with conflicting or outdated views of business operations. While data lakes, warehouses and lakehouses remain important for analytics and reporting, AI-driven decisions increasingly require information that reflects the current state of the business.
A Streamhouse is designed to provide that operational context by continuously capturing, processing, governing and serving business data across systems. It works alongside existing data warehouses and lakehouses rather than requiring enterprises to replace them.
For example, when an airline cancels a flight, its operations, scheduling and reservation systems may hold different information about aircraft location, departure times and seat availability. An AI rebooking agent relying on inconsistent updates could offer a passenger an itinerary that appears valid in one system but fails in practice. A Streamhouse brings these changes into a shared, continuously updated view, enabling agents and applications to make decisions using consistent information.
“The next era of enterprise AI will be won by the agents that know what’s happening in the business the moment they act.”
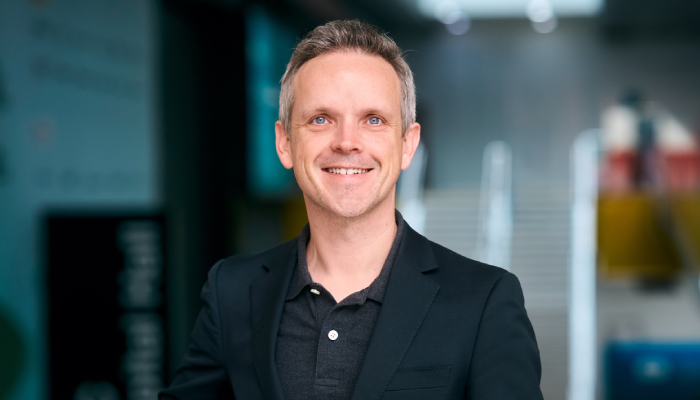
— Shaun Clowes, General Manager, Confluent and Data, IBM
Accenture is already using a Streamhouse architecture powered by Confluent to connect data across its global operations. Thomas Mahaffey, SAI Chief Data Strategist at Accenture, said the approach has helped the company move beyond legacy batch and point-to-point architectures, reducing data duplication and operational overhead. The company has reduced its time-to-insight from months to days while improving reporting across its workforce of 800,000 employees in more than 120 countries.
Confluent’s Data Streaming Platform is built around Apache Kafka and the Kora engine, with Apache Flink supporting data processing and enrichment. Its 150-plus managed and custom connectors bring information from enterprise systems into streaming pipelines, while governance capabilities cover data discovery, classification, lineage, quality, encryption, schemas and access controls.
The new Query pillar provides three ways to make streaming data available to different workloads. Tableflow exposes streaming data to warehouses and lakehouses through open table formats. The Real-Time Context Engine serves business context to AI agents through the Model Context Protocol (MCP). Lightning Tables provides applications with SQL and API access to the latest state of business data.
Lightning Tables is now generally available on AWS through Confluent Cloud. It acts as a managed, read-only serving layer that materialises Kafka data into continuously updated tables, reducing the need for separate databases, caches and ETL pipelines. In Confluent’s internal testing, it delivered approximately 100 milliseconds of data freshness, query latency of 10–100 milliseconds and throughput exceeding 1,000 queries per second. Actual performance varies by configuration and workload.
Shaun Clowes, General Manager, Confluent and Data, IBM, said the architecture would help enterprises move from decisions based on historical snapshots to actions grounded in current business conditions.
The introduction of Streamhouse reflects a shift in enterprise data architecture as organisations prepare to deploy AI agents across operational workflows. The challenge is no longer simply making data available to AI, but ensuring that agents can access governed, consistent and current information at the moment they act.
